Claude rendered 223 clips of my game's robot voice, and couldn't hear any of them
I asked for ten experiments to make the dive monitor in BLACKWATER sound less like a wobble. In under three hours and seven rounds, Claude rendered 223 clips it had no way to listen to, checked every one with a transcriber and a loudness meter, and left the choosing to my ears. The clips are below, so you can hear them at the same moment I did.
On 1 October I asked Claude to make REMORA, the robot voice in the diver’s ear in BLACKWATER, sound cooler. Two hours and 48 minutes later there were 223 clips on a listening page, seven rounds of them, and a treatment I liked. Claude heard none of it. It said so at the top of the page: “I can’t listen to audio. My picks come from the measurements and from what each technique is known to do. Your ears decide.”
That split is what made it work. Claude did everything that can be measured: same line, same loudness, a speech-to-text check on every clip, a spectrogram of each. I did the one thing that can’t be, which was listening, and each of my answers set up the next round.
Nothing here is in the game yet. Every clip and spectrogram below is the session’s own render.
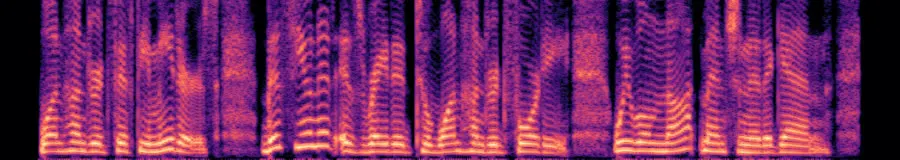
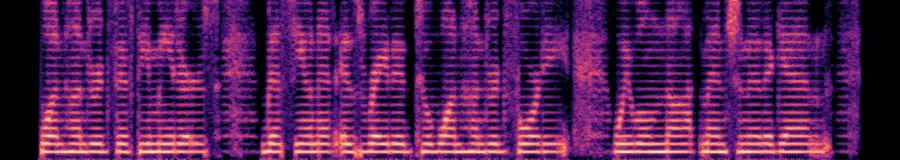
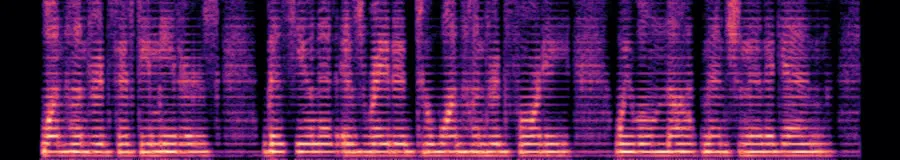
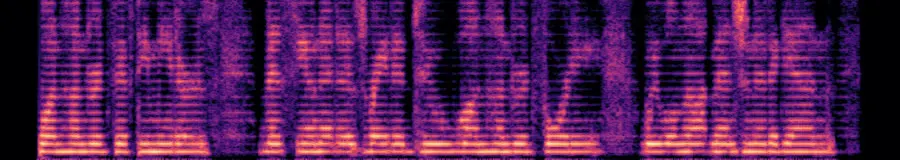
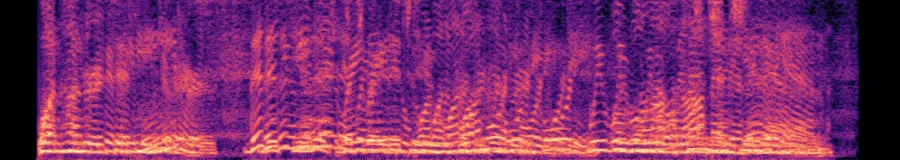
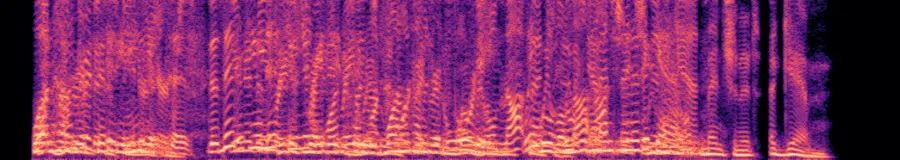
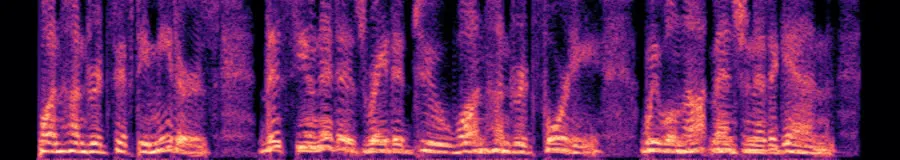
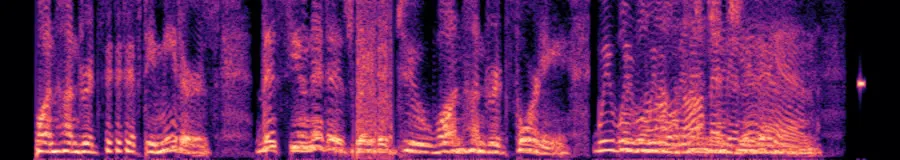
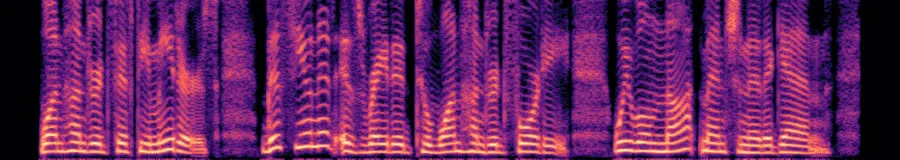
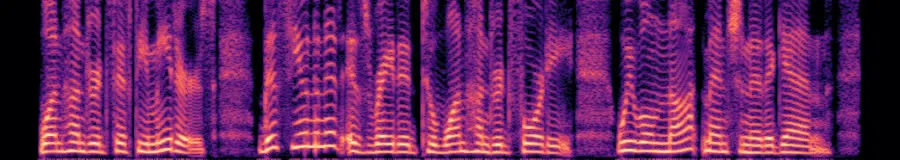
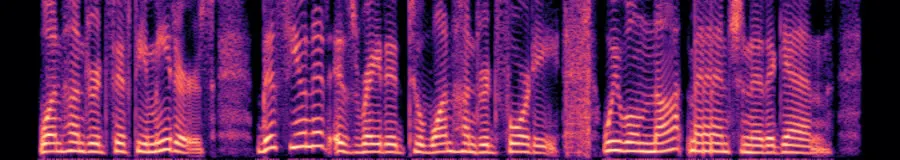
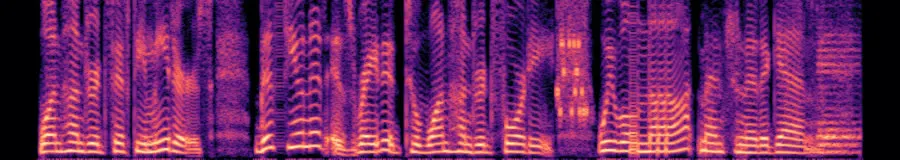
Each player below keeps the playhead when you switch clips, so the same word comes through each treatment, and A/B flips to the block’s reference at the same moment. The picture is the clip’s spectrogram: time left to right, pitch bottom to top. Every clip was normalised to −18 LUFS, so none wins by being louder.
Round 1: what ships, and ten ways out
My prompt asked for at least ten experiments, “some could just be special effects on top of the generated audio clips”, and two stacks I wanted to hear: her line generated five times and played at once, and five different voices saying it together. “Don’t add it to the game yet, this is just an experiment.”
The line was the one she says at 150 metres: “One hundred fifty meters. This unit is rated to one hundred forty. We will not mention it again.” What ships today is a 52 Hz volume wobble squeezed through a phone band. The session’s own summary of round 1 was that the biggest step toward “robot” was flattening her pitch onto one note.
The stacks I asked for
The two I’d asked for came out the way the spectrogram says: five takes of the same line breathe and pace differently, so the words drift apart and the pauses fill in. Five different voices piled up worse, and it was the only clip in round 1 the transcriber got wrong (it heard “meters” as “units”). Claude’s fix was to re-time every word of takes 2 to 5 onto take 1, which ElevenLabs makes possible because it returns a timestamp for every character. Locked, the pauses come back.
Then I asked for 12 “but also add the glitch effect and leave the last few words unsynchronized”, and six minutes later for “staggering just the words 140”: the number the unit is rated to, said five times, each take a little later than the last.
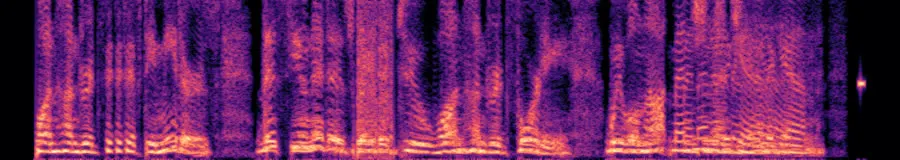
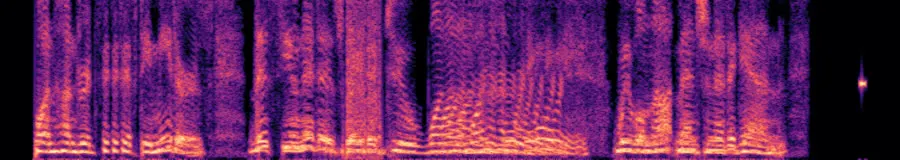
My answer to 18: “okay, I like this effect, but we can only use this for one or two lines.” A voice that does that on every line stops meaning anything. So the next ask was glitches for her ordinary lines, and whether there was anything we could install to get better effects.
Round 4: a glitch per line, rolled
Claude sent a Sonnet 5.5 agent to research plugins and libraries while it built ten glitches and two ways of combining them, each placed automatically from the line’s word timings and never on a number, so she can glitch on “unit” but never on “forty”. G11 is the one meant for everyday use: each line rolls one main glitch, sometimes a second at the end or in a pause, seeded by the line’s id so the same line always sounds the same. Across her 29 scripted lines it came out as 11 lines with one event, 15 with two and 3 with three. The block below has three of its rolls on the same line.
Round 5: effects that never stop
Then I noticed something about all of it: “all the ones you used were just things that just happen once in the sound clip.” I asked for persistent effects, for Kilohearts Essentials and Glitch² to be installed if they were easy, and for a showcase of what it could do to audio without ElevenLabs at all.
Glitch² went in, run from Python through DawDreamer in its own environment because the plugin needs a host with a clock. Kilohearts didn’t: it needs an account and its own installer, which the session said it couldn’t do for me. The toolbox came back with 36 techniques and 10 sound effects synthesised from nothing. And twelve persistent effects, which is where I found it.
“data shimmer! that is the one!” P7 is three copies of her drifting 11 to 25 milliseconds behind on slow, unrelated wobbles. I also liked P12, P10 and P9, and wrote that G11 was “amazing too”.
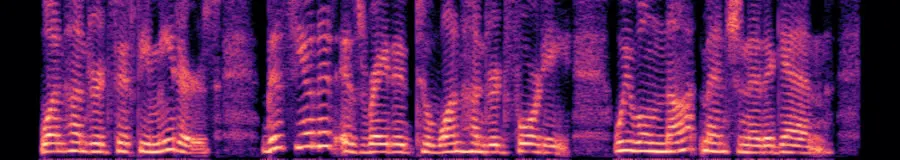
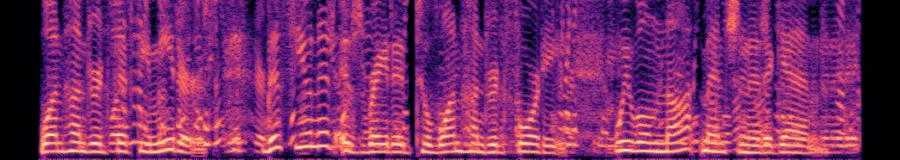
Glitch²’s factory bank loads a random set of programs every time, so the session pinned the 16 it rendered and ran each over a plain take of another line, “Visibility zero. Hold the line. The line does not panic.” The transcriber is the only judge Claude had, and it was blunt: one program kept all ten words, and six kept none.
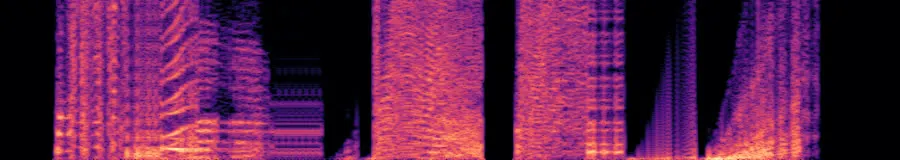
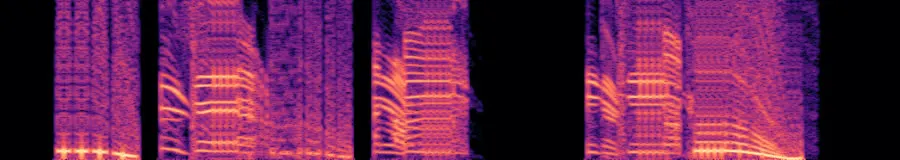
Rounds 6 and 7: putting the picks together
Round 6 mixed my five picks eight ways on four new lines. My answer: “I like everything together but the shimmer channel. The echo should be treated as a glitch. And some voicelines should have the 5 eleven labs voices layer word and staggering as it’s bases voice line with all the effects on top.” Round 7 did exactly that and called it REMORA v1. V1 is for ordinary lines: the glitch roll, with the halo cut down to a brief “memory echo” on 40 % of lines, then the shimmer and the whisper, in mono. V2 is for the one or two special lines: the shipped take plus four more, word-locked, with one word staggered and the glitches kept off it.
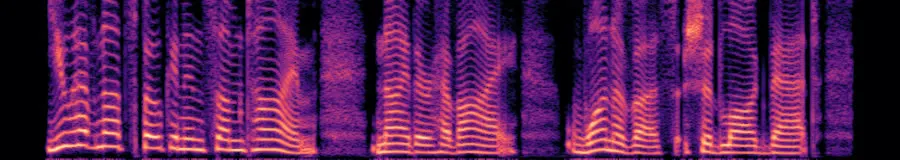
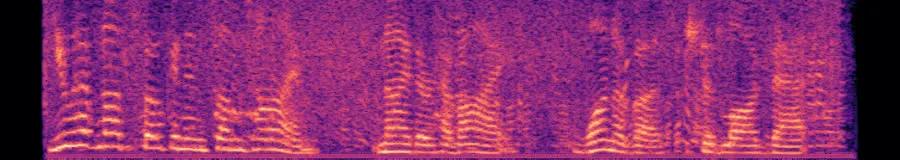
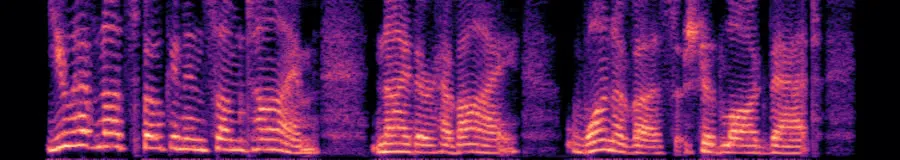
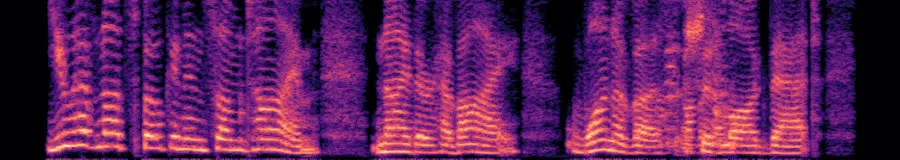
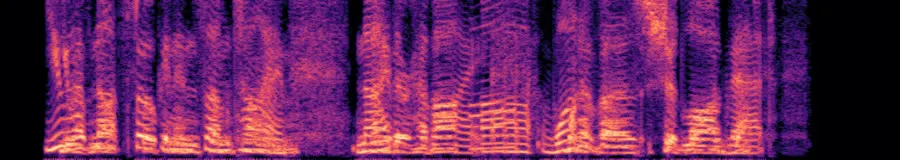
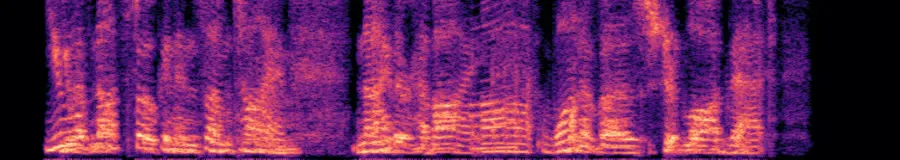
And her first line, where the staggered word is her own name:
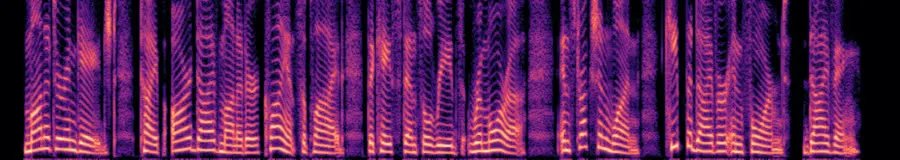
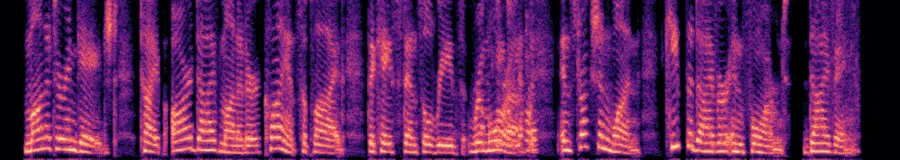
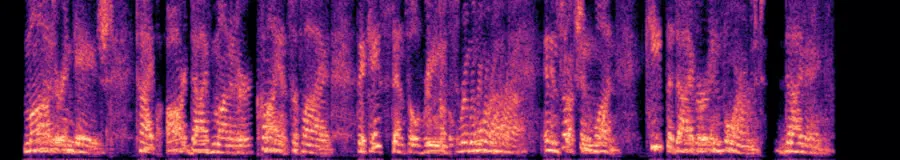
The transcriber got every word of 29 of round 7’s 32 clips; the other three kept every word and picked up an extra “uh” where the staggered “I”s trail off. Which lines get V2 isn’t decided yet.
What the numbers could and couldn’t do
The session never guessed at what sounded good. It measured what it could and printed it on the page: the loudness match, the pitch spread in semitones, the transcriber’s word count, how much of each line an effect actually touched. Those numbers cleared out what didn’t work before I heard anything (six Glitch² programs that erased the line, a pile-up that turned “meters” into “units”), and they couldn’t tell me a thing about which of the rest was good.
The useful thing an agent did here was make my ears fast. Same line, same level, same moment, one click between them, so the only difference left was the one I was there to judge. Seven rounds took 2 hours 48 minutes and $32 at API list prices, almost all of it Opus 5.5, with one Sonnet 5.5 research agent. Of everything in REMORA v1, only the five-take stack was in my first prompt. The shimmer, the whisper and the echo are things I said yes to after hearing them.